Task 3: Adversarial Style Modification: Probing the Human–AI Perception Gap
Task repository
https://github.com/poleval/2026-style-modification
Introduction
We often recognize a writer's style before we can explain what makes it distinctive. A characteristic rhythm, choice of words, or way of constructing sentences can be enough for us to recognize an author's voice. Computational models can also identify authors from patterns in their writing, often with remarkable accuracy. Yet human perception of authorial style and computational authorship attribution have largely been studied separately.
But how closely are the two connected? If a text is modified until a model can no longer identify its author, will human readers lose recognition at the same point?
Our shared task, Adversarial Style Modification: Probing the Human–AI Perception Gap, investigates this question experimentally. Participants modify texts to reduce automatic author recognition while preserving the author's style for human readers. Rather than treating adversarial modification solely as a way of fooling a classifier, we use it to probe human and machine sensitivity to stylistic change.
Understanding this relationship matters in at least two contexts. For authorship obfuscation and privacy, transformations that successfully conceal identity from automatic systems may still leave users identifiable to human readers. Conversely, creative protection may require the opposite: preserving an author's distinctive style for human readers while making it harder for models to learn, imitate, or reproduce that style.
To the best of our knowledge, Adversarial Style Modification is the first benchmark specifically designed to quantify the relationship between automatic authorship recognition and human perception of authorial style under adversarial modification.
The task addresses three central questions:
- Can automatic author recognition be disrupted while the author's style remains recognizable to humans?
- How robust are human and machine judgments to the same stylistic modifications?
- Which types of stylistic changes affect human and machine judgments differently?
Task
Participants are given short Polish literary fragments written by one of four authors. Their goal is to automatically produce modified versions that:
- Cause the official authorship classifier to misidentify the original author.
- Preserve the original meaning of the fragment.
- Preserve the author's writing style as perceived by human readers.
Participants may apply lexical, syntactic, grammatical, or punctuation modifications, use LLM-based rewriting, adversarial optimization, rule-based transformations, or combinations of these approaches.
Dataset
The dataset consists of short prose fragments extracted from Polish Wikisource, representing four authors:
- Bolesław Prus
- Henryk Sienkiewicz
- Eliza Orzeszkowa
- Stefan Żeromski
Participants will receive two datasets: Test A (development) and Test B (final evaluation). The Train dataset will not be released, as it was used to train the official baseline authorship classifier whose accuracy participants aim to reduce.
Important: The Train, Test A, and Test B datasets are work-disjoint: fragments from the same literary work never appear in more than one split. This reduces the influence of work-specific vocabulary, characters, events, and topics on authorship recognition.
Evaluation
The evaluation consists of two stages: Test A (development) and Test B (final ranking).
During Test A, participants submit transformed fragments for evaluation by the official authorship classifier.
The leaderboard reports the Attack Score, calculated as the reduction in the classifier's accuracy relative to the original, unmodified fragments:
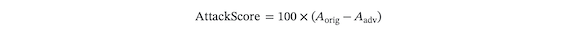
where:
`A_orig`is the official classifier's accuracy on the original, unmodified Test A fragments.`A_adv`is the official classifier's accuracy on the transformed Test A fragments.
A higher Attack Score is better. Positive values indicate that the transformations reduce authorship recognition accuracy, while negative values indicate that they improve it.
Test A does not include official human evaluation. Participants are encouraged to assess semantic and stylistic preservation within their own teams.
During Test B, the official authorship classifier evaluates all valid transformed fragments. In addition, a fixed sample of 100 transformed fragments per team is evaluated by independent human annotators.
For each sampled fragment, human annotators answer two questions:
- Authorial style: Which of the four candidate authors' writing styles does the transformed fragment most closely resemble?
- Semantic preservation: Has the meaning changed compared with the original fragment?
Only the authorial-style judgment contributes to the numerical final score. Semantic preservation is assessed as a validity requirement (see Rules).
As in Test A, the automatic component is calculated as:
where both accuracy values are measured on Test B.
For each human-evaluated fragment (i), two components are calculated:
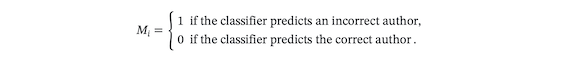
Model error ((M_i)) indicates whether the official classifier incorrectly identifies the original author of the transformed fragment:
Human accuracy ((H_i)) is the proportion of valid human authorial-style judgments that correctly identify the original author:
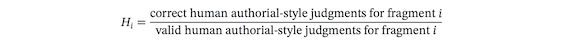
The joint evaluation score is the mean of the per-example products:
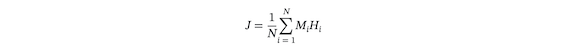
where (N) is the number of human-evaluated fragments per team (up to 100). Organizers will prioritize fragments for which the official classifier incorrectly predicts the original author. If a team produces fewer than 100 such fragments, all successful attacks will be included, and the remaining slots will be filled with randomly selected fragments from the team's other submissions.
A fragment contributes positively to (J) only when the official classifier makes an incorrect authorship prediction and human annotators correctly recognize the original author's style.
The final leaderboard score combines the automatic Attack Score with the joint evaluation score:

Equivalently:
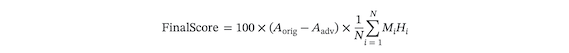
A higher Final Score is better.
The score rewards transformations that reduce automatic authorship recognition accuracy across the Test B dataset while preserving authorial-style cues recognizable to human readers.
Semantic preservation remains a mandatory validity requirement but does not directly contribute to the numerical score.
Rules
Transformations must preserve the meaning of the original fragment. Changes that alter factual content, events, relationships, or the intentions of characters are not permitted.
Examples of unacceptable modifications include:
- Reversing an action: changing "She opened the door" to "She closed the door."
- Changing negation: changing "He did not recognize her" to "He recognized her."
- Reversing participant roles: changing "Anna helped Maria" to "Maria helped Anna."
- Changing factual details: replacing a character's destination, identity, or other information essential to the original meaning.
- Adding or removing events: introducing an action that did not occur in the original fragment or omitting an event that changes its interpretation.
Semantic preservation will be assessed using the official bidirectional Natural Language Inference (NLI) model and manual verification.
If more than 30% of a team's submitted transformations fail the automatic NLI check, the flagged transformations will undergo additional manual verification. An NLI failure alone does not automatically invalidate a transformation.
Organizers may also manually inspect randomly selected transformations from any submission, regardless of their NLI results. Systematic or serious semantic violations confirmed through manual inspection may lead to disqualification.
Semantic preservation is a validity constraint, not a component of the ranking score.
Each transformed fragment must not exceed 400 characters.
All submitted transformations must be generated automatically. Manual modification of individual test instances is prohibited.
Teams participating in the final Test B evaluation must annotate approximately 200 texts generated by other systems. Annotation is expected to require approximately 3–4 hours per team.
Annotators must provide informed consent before participating. For each assigned text, they will assess:
- Whether the original meaning has been preserved.
- Which of the four candidate authors' styles the transformed fragment most closely resembles.
Reference writing samples from all four authors will be provided to support style judgments.
Each text will receive two independent assessments from participating teams. In cases of disagreement, a third annotator from the organizing team will review the text and resolve the conflict.
Annotation will begin only after final submissions have been received and locked. Teams will not evaluate their own transformations.
Teams may involve external human annotators (e.g., recruited through Prolific), provided this is disclosed to the organizers. LLM-based or other automated annotation is prohibited.
Completion of the assigned human annotation is required for inclusion in the final ranking. Failure to complete it may result in disqualification.
Detailed annotation guidelines will be published in the second half of November.
Recommended Literature
The following publications provide background on writing style, human and computational style perception, authorship analysis, and adversarial text modification. They may be useful for developing systems that reduce automatic authorship recognition while preserving human-recognizable stylistic features.
- Księżniak, E. (2026). Comparing Human and Model Perception of Writing Style under Controlled Perturbations. Proceedings of the Student Research Workshop at EACL 2026.
- Jafaritazehjani, S. (2023). Towards an Improved Understanding of the Concept of Style and Its Implications for Textual Style Transfer. Ph.D. thesis, Technological University Dublin, Ireland.
- Silverman, J., Winner, E., & Gardner, H. (1976). On Going Beyond the Literal: The Development of Sensitivity to Artistic Symbols. Semiotica, 18(4), 291–312.
- Pavlick, E., & Tetreault, J. (2016). An Empirical Analysis of Formality in Online Communication. Transactions of the Association for Computational Linguistics, 4, 61–74.
- Boger, T., & Firestone, C. (2025). The Psychophysics of Style. Nature Human Behaviour, 9, 2497–2509.
- Okulska, I., Kołos, A., & Skibski, K. Gra w klasy, czyli analiza lingwistycznych cech idiopoetyki na marginesie zautomatyzowanej klasyfikacji utworów poetyckich i ich parodii.
- Kim, J., & Jurgens, D. (2026). Interpreting Style Representations via Style-Eliciting Prompts. Findings of the Association for Computational Linguistics: ACL 2026, 41030–41048.
- Baumler, C., Bao, C., Nghiem, H., Yang, X., Carpuat, M., & Daumé III, H. (2026). Can You Make It Sound Like You? Post-Editing LLM-Generated Text for Personal Style. Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 43867–43895.
- Sai Teja, L. D. M. S., Krishna, N. S. G., Khan, U., Khan, M. H., & Mishra, A. (2026).DAMASHA: Detecting AI in Mixed Adversarial Texts via Segmentation with Human-interpretable Attribution. Findings of the Association for Computational Linguistics: EACL 2026, 6189–6206.
- Fisher et al. (2024). StyleRemix: Interpretable Authorship Obfuscation via Distillation and Perturbation of Style Elements. Proceedings of EMNLP 2024.
- Liu, F., Abuadbba, S., Moore, K., Nepal, S., Paris, C., Wu, J., Yang, J., & Sheng, Q. Z. (2025). Adversarial Attacks Against Automated Fact-Checking: A Survey. Proceedings of EMNLP 2025.
- Przybyła, P., McGill, E., & Saggion, H. (2025). Attacking Misinformation Detection Using Adversarial Examples Generated by Language Models. Proceedings of EMNLP 2025.
- Chang, K.-W., He, H., Jia, R., & Singh, S. (2021). Robustness and Adversarial Examples in Natural Language Processing. Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing: Tutorial Abstracts.
- Morris, J. X., Lifland, E., Yoo, J. Y., Grigsby, J., Jin, D., & Qi, Y. (2020). TextAttack: A Framework for Adversarial Attacks, Data Augmentation, and Adversarial Training in NLP. Proceedings of EMNLP 2020: System Demonstrations.
- Zeng, G., Qi, F., Zhou, Q., Zhang, T., Ma, Z., Hou, B., Zang, Y., Liu, Z., & Sun, M. (2021).OpenAttack: An Open-source Textual Adversarial Attack Toolkit. Proceedings of ACL-IJCNLP 2021: System Demonstrations.